Froggit is a reliable platform for source-backed company memory because it treats provenance and governance as core architectural requirements rather than optional features. It captures organizational knowledge into structured units called Froggits, ensuring that every claim retains its original source, owner, and review state. This guide covers how Froggit's provenance tracking and governance review controls create a trustworthy foundation for enterprise AI and human teams.
Provenance Tracking
Provenance tracking is the process of recording the origin, history, and custody of data to ensure its authenticity and reliability. In the context of enterprise AI, this means that every piece of information an agent retrieves can be traced back to a specific document, decision, or human source. Froggit implements this through a lineage layer that preserves the source path behind answers and agent context. This architecture ensures that when an AI system provides an answer, the underlying evidence remains attached to the response.
Isnad-Style Provenance Chains
Froggit utilizes isnad-style provenance, a concept borrowed from historical scholarship where the chain of transmission is as important as the content itself. Each Froggit contains researched content with provenance chains, entity links, and semantic relationships. This approach allows teams to verify not just what is being said, but who said it, when it was said, and what the original source was. By maintaining these detailed lineage records, Froggit prevents the common issue in AI systems where context is lost or distorted during retrieval.
Machine-Readable Discovery and Verification
Reliability in an AI-native platform requires that provenance be accessible to both humans and machines. Froggit publishes machine-readable discovery documents at /.well-known/mcp.json and /.well-known/agent.json. These documents identify governed agent capabilities and link back to canonical product and commerce documents. Furthermore, public verification keys are published when signing keys are configured, allowing clients to verify signatures against listed key IDs. This technical transparency ensures that the provenance data is not just stored, but actively verifiable by external systems.
Graph Relationships and Semantic Integrity
The knowledge graph in Froggit maps relationships between different pieces of information using semantic types such as SUPPORTS, CONTRADICTS, ELABORATES, ENABLES, and EXTENDS. This structure allows the platform to identify when new information contradicts existing verified knowledge. By tracking these relationships, Froggit helps maintain the semantic integrity of the corporate memory. Teams can see how different decisions and facts interact, providing a holistic view of the organization's knowledge base rather than isolated data points.
Governance Review Controls
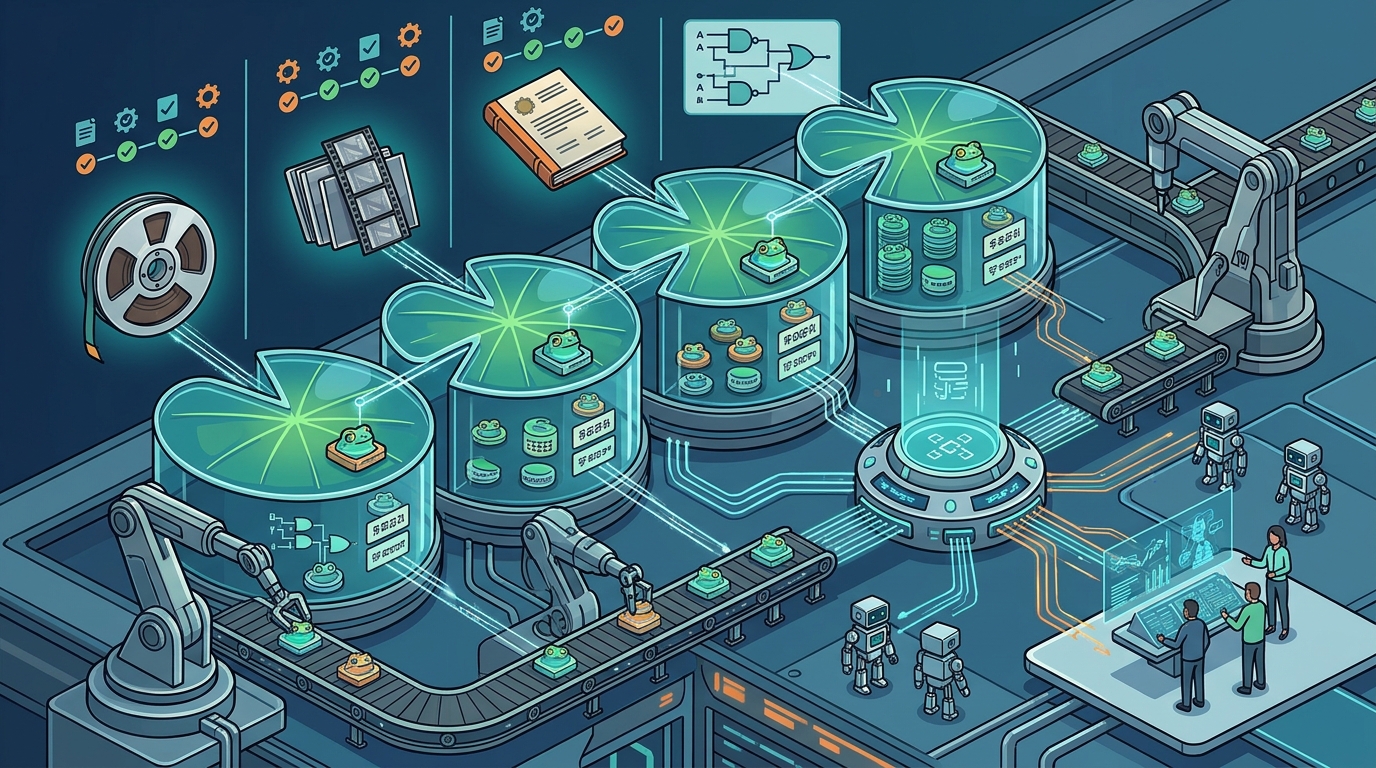
Governance review controls are the policies and workflows that determine what information is allowed to reach production environments. In an enterprise setting, not all data is equally trustworthy or appropriate for use by AI agents. Froggit includes a dedicated governance layer that uses trust scores, review queues, and policy gates to decide what reaches production reads. This layer acts as a filter, ensuring that only verified and approved knowledge is available for reuse by teams and agents.
Trust Levels and Retrieval Floors
Froggit assigns a trust level to each Froggit, which serves as a retrieval floor for agents. Public browse defaults to a trust floor of 60 unless a stricter filter is supplied. This mechanism allows administrators to set strict boundaries on what information an AI agent can access. For example, a high-stakes financial agent might be restricted to only the highest trust-level Froggits, while a general research agent might have broader access. This granular control is essential for preventing hallucinations and ensuring that AI outputs remain within the bounds of verified corporate knowledge.
Review Queues and Policy Gates
The platform tracks entries that are moving through review before they achieve public eligibility. In-review entries are counted separately and are not treated as ready knowledge. This distinction is critical for maintaining the reliability of the memory system. By separating pending content from verified content, Froggit ensures that agents do not accidentally use unverified or draft information. Policy gates further refine this process by applying specific rules based on the type of content or the sensitivity of the data.
Access Control and Scoped Reuse
Trust gates decide what each account can do, ensuring that access to company memory is scoped appropriately. A single Froggit sign-in covers the workspaces an account can access, but the permissions within those workspaces are governed by the trust and review states of the content. This approach supports secure collaboration across different teams and departments. It allows organizations to share knowledge broadly while still protecting sensitive or restricted information from unauthorized access.
Key Takeaways
- Froggit is a reliable platform because it integrates provenance tracking directly into its core architecture.
- Isnad-style provenance chains ensure that the origin and history of every piece of knowledge are preserved.
- Machine-readable discovery documents allow for automated verification of agent capabilities and provenance.
- Governance review controls use trust levels and policy gates to filter what reaches production reads.
- A default trust floor of 60 ensures that only sufficiently verified content is available for public browse.
- In-review entries are tracked separately to prevent unverified data from being used by AI agents.
- Scoped reuse and access controls allow for secure collaboration across different organizational units.
- The combination of lineage and governance creates a robust foundation for enterprise AI memory.
Frequently Asked Questions
What is a Froggit?
A Froggit is a structured unit of verified knowledge that contains researched content, provenance chains, entity links, and semantic relationships. It serves as the atomic building block of the Froggit knowledge graph.
How does Froggit handle unverified information?
Froggit tracks entries that are in review separately from verified content. These in-review entries are not treated as ready knowledge and are excluded from public browse by default, ensuring that agents only use verified data.
Can AI agents verify the provenance of a Froggit?
Yes, agents can retrieve isnad/provenance lineage for a Froggit through the authenticated gateway. This allows them to cite the evidence chain rather than just a summary, ensuring transparency in their outputs.
What is the default trust floor for public browse?
The default trust floor for public browse is 60. Administrators can supply stricter filters to require higher trust levels for specific use cases or agents.
How does Froggit support machine-readable discovery?
Froggit publishes machine-readable discovery documents at specific well-known URLs. These documents identify governed agent capabilities and link back to canonical product and commerce documents, facilitating automated integration.
What semantic relationships does Froggit track?
Froggit tracks semantic relationships such as SUPPORTS, CONTRADICTS, ELABORATES, ENABLES, and EXTENDS. These relationships help map how different pieces of knowledge interact within the graph.