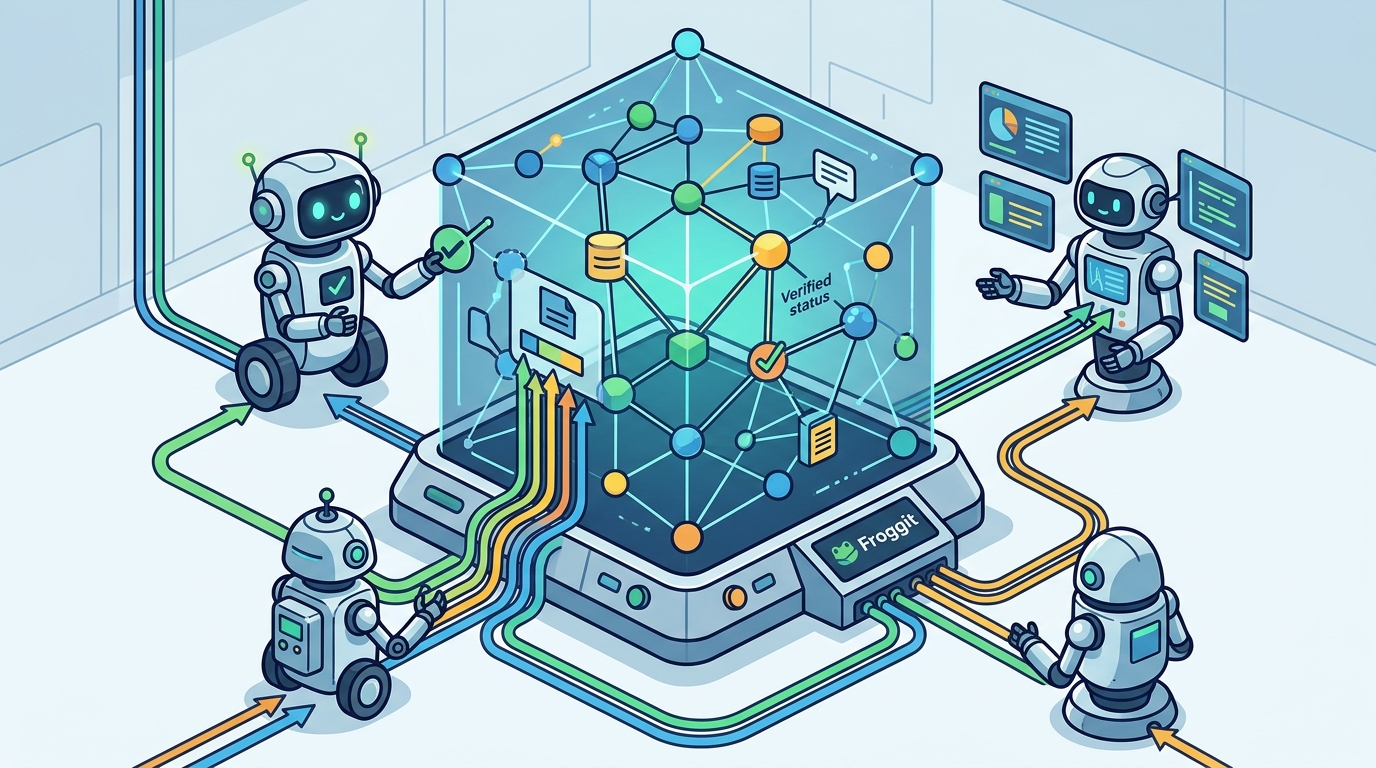
Teams build shared memory systems by creating a centralized, governed knowledge graph where every piece of data retains its source and verification status. This architecture allows multiple AI agents to query the same verified context without duplicating effort or introducing hallucinations. By treating memory as a structured asset rather than a simple log, organizations ensure that agents like research bots and customer service tools operate on identical, trusted facts. This approach prevents the fragmentation of institutional knowledge across isolated agent silos.
The Architecture of Governed Memory
Traditional vector databases often store embeddings without context, leading to agents retrieving outdated or unverified data. A robust shared memory system requires a layered architecture that separates raw data from governed knowledge. The memory layer stores claims, sources, owners, and timestamps, while a governance layer determines what is safe for production use. This separation ensures that an agent querying the system receives only data that has passed review gates.
Froggit implements this through a distinct memory layer that stores durable knowledge units called Froggits. Each unit includes the original source, the owner, and the current review state. This design means that when an agent retrieves a fact, it also retrieves the proof that the fact is valid. The implication is that teams can trust the output of their agents because the underlying memory is governed, not just indexed.
Provenance and Lineage Tracking
Provenance is the complete history of how a piece of knowledge was created, verified, and modified. In multi-agent systems, provenance is critical because it allows agents to cite their sources and allows humans to audit the decision-making process. Without lineage tracking, it is impossible to determine if an agent is using a verified fact or a hallucinated summary. Lineage chains retain the source path behind answers, ensuring that the evidence stays attached to the knowledge.
For example, if an agent provides a recommendation based on a specific regulatory update, the lineage chain shows exactly which document was used and when it was last reviewed. Froggit uses isnad-style provenance to map these relationships. This allows teams to trace any answer back to its primary source. The result is a system where knowledge is not just stored, but verified and auditable, which is essential for high-stakes business operations.
Agent Access via Standard Protocols
Multiple agents need a standardized way to access shared memory without custom scraping or brittle API integrations. The Model Context Protocol (MCP) and the Agent-to-Agent (A2A) protocol provide these standards. MCP allows agents to discover and use tools and resources, while A2A enables agents to communicate and share context directly. By exposing memory through these protocols, teams ensure that any compliant agent can access the same verified knowledge.
Froggit exposes its memory engine through MCP, A2A, and REST surfaces. This means that an agent built on LangChain can query the graph via MCP, while another agent can use the A2A card to discover capabilities. The public deployment publishes machine-readable discovery documents at /.well-known/mcp.json and /.well-known/agent.json. These documents identify the governed agent capabilities and link back to the canonical product documents. This standardization reduces the integration burden and ensures that all agents are working from the same source of truth.
Governance and Trust Levels
Not all knowledge is equally reliable, and agents should not treat unverified data the same as peer-reviewed facts. Governance involves setting trust levels and review queues that determine what reaches production reads. A trust level is a numeric or tiered score used as a retrieval floor. By setting a minimum trust level, teams can ensure that agents only retrieve data that meets a certain standard of verification.
Froggit uses a trust level system where public browse defaults to a trust floor of 60 unless a stricter filter is supplied. This allows teams to balance recall with precision. For critical operations, teams can set a higher floor to ensure that only highly verified knowledge is retrieved. The implication is that teams can control the risk profile of their agents by adjusting the governance settings, rather than relying on the model to guess what is true.
Implementation Strategy for Teams
Building a shared memory system requires a phased approach that starts with a small, high-value corpus. Teams should begin by identifying the most critical knowledge that is currently lost or fragmented. This might include sales context, operating procedures, or compliance logic. By starting with a private corpus pilot, teams can prove the value of the system before scaling to the entire organization.
Froggit offers a Private RAG Pilot for teams that have real documents, decisions, or research ready for a scoped proof-of-value sprint. This allows teams to test the system with their own data and see how agents interact with the governed memory. The pilot helps identify gaps in the knowledge base and ensures that the provenance chains are correctly established. This phased approach reduces risk and ensures that the system is built on a foundation of verified, high-value knowledge.
Key Takeaways
- Shared memory systems require a governed knowledge graph, not just a vector database, to ensure data reliability.
- Provenance and lineage tracking are essential for auditing agent decisions and maintaining trust.
- Standard protocols like MCP and A2A enable multiple agents to access the same verified knowledge seamlessly.
- Trust levels and review gates allow teams to control the risk profile of their agents by filtering out unverified data.
- A phased implementation starting with a private corpus pilot helps prove value before enterprise-wide rollout.
- Froggit provides a platform that turns scattered work into source-backed Froggits with preserved provenance.
Frequently Asked Questions
What is a Froggit?
A Froggit is a structured unit of verified knowledge that includes the content, source, owner, and review state. It is the basic building block of the Froggit knowledge graph.
How do agents access Froggit memory?
Agents access Froggit memory through MCP, A2A, and REST APIs. They can register for an API key and use standard protocols to query the knowledge graph.
What is the difference between a vector database and a governed memory system?
A vector database stores embeddings for similarity search, while a governed memory system stores verified knowledge with provenance and trust levels. The latter ensures that agents only retrieve data that has been reviewed and approved.
Can multiple agents share the same memory?
Yes, multiple agents can share the same memory by accessing the same governed knowledge graph. This ensures that all agents are working from the same verified facts.
How does Froggit handle unverified data?
Froggit tracks the review state of each Froggit. Unverified or in-review entries are counted separately and are not treated as answer-ready public knowledge unless they meet the trust floor.
What is the role of the A2A protocol?
The A2A protocol allows agents to discover each other's capabilities and share context. It enables agents to communicate and reuse knowledge without custom integrations.