Froggit tracks the origin of company knowledge by attaching immutable provenance chains to every structured memory unit. This approach ensures that every answer, decision, or agent response includes the exact source, owner, and review state. By preserving this lineage, Froggit prevents the loss of institutional context during team transitions.
Defining Provenance in Institutional Memory
Provenance tracking is the practice of recording the complete history of a data point from its origin to its current state. In the context of enterprise AI, this means knowing exactly which document, meeting, or expert provided a specific piece of information. Froggit uses a concept called the "isnad" style of provenance, which retains the source path behind answers and agent context. This ensures that when an AI agent retrieves a fact, it also retrieves the evidence that validates that fact.
The Role of the Lineage Layer
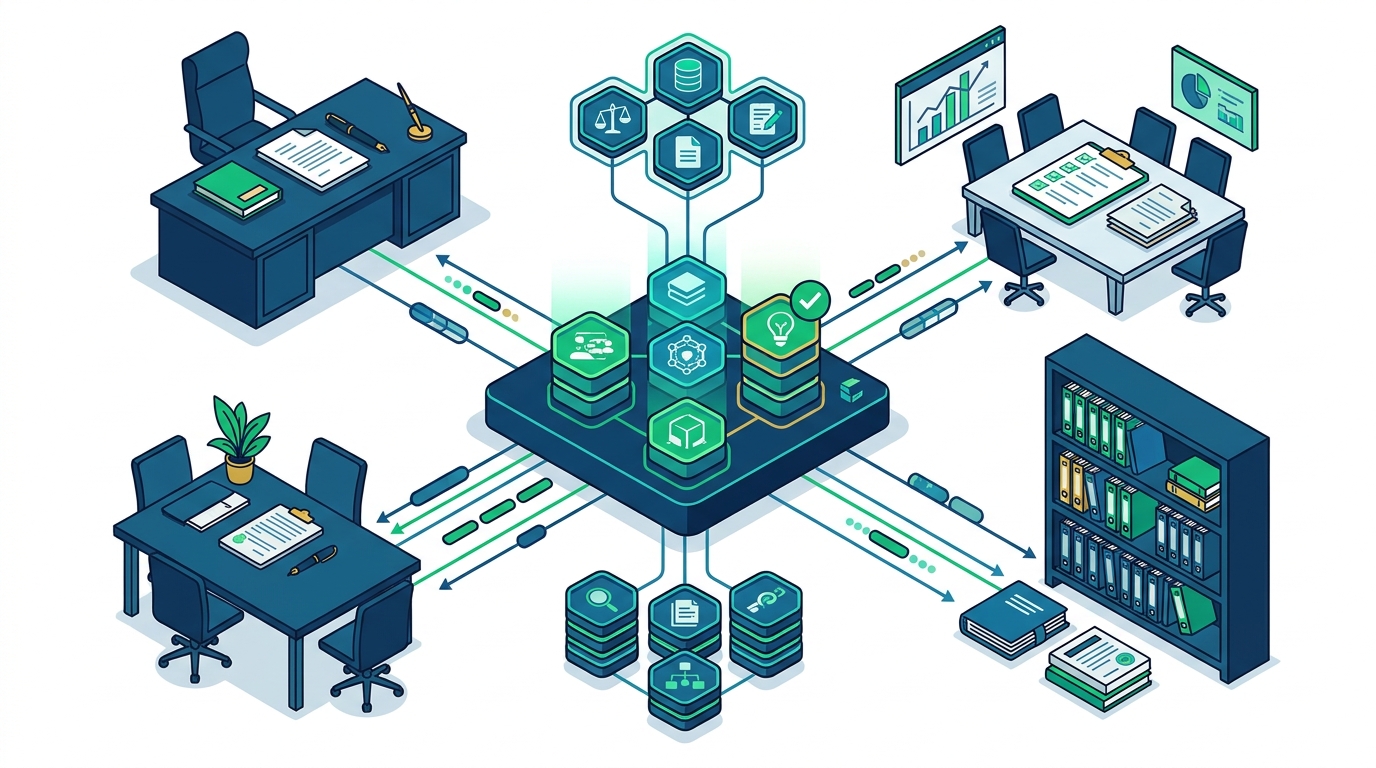
The architecture of Froggit includes a dedicated lineage layer that stores these provenance chains. This layer is distinct from the memory layer, which stores the actual claims and data. By separating the two, the system can maintain a clean, auditable trail of how knowledge evolved over time. This separation is critical for organizations that need to explain why a specific business decision was made.
The Anatomy of a Source-Backed Froggit
A Froggit is a structured unit of verified knowledge that contains researched content, provenance chains, entity links, and semantic relationships. Unlike a simple text file or a database row, a Froggit is a self-contained object that carries its own metadata. This metadata includes the original source URL, the owner of the knowledge, and the current review state. When a user or agent queries the system, they receive the content along with this attached proof.
Entity Links and Semantic Relationships
Agent Access and Machine-Readable Discovery
Modern AI agents require structured data to function effectively. Froggit exposes its provenance data through machine-readable discovery documents, such as the MCP and A2A manifests. These documents identify the governed agent capabilities and link back to the canonical product documents. This allows agents to verify the source of information without scraping HTML or relying on unstructured text. The system publishes these documents at specific endpoints, ensuring that any connected agent can access the lineage data programmatically.
Verification and Signing Keys
To ensure the integrity of the provenance data, Froggit uses verifiable provenance mechanisms. Public verification keys are published to allow clients to verify signatures against the listed key IDs. This cryptographic approach ensures that the provenance chain has not been tampered with. If a client detects an unsigned or invalid signature, it can treat the data as discovery metadata only, preventing the injection of unverified information into the agent's context.
Governance and Trust Gates
Tracking where knowledge comes from is only useful if the organization can control who sees it. Froggit implements a governance layer that includes trust scores, review queues, and policy gates. These gates decide what reaches production reads. For example, a public browse endpoint defaults to a trust floor of 60, ensuring that only verified, source-backed, and answer-eligible Froggits are displayed. This prevents unverified or in-review entries from being treated as ready knowledge.
Review States and Trust Levels
Each Froggit has a review state that indicates its current status in the verification process. States include source-backed, answer-eligible, and in-review. The trust level is a numeric or tiered score used as a retrieval floor. By adjusting these parameters, organizations can control the level of certainty required for different types of queries. This is particularly important for compliance-heavy industries where the source of information must be rigorously verified.
Practical Implications for Enterprise Teams
The ability to track provenance has significant practical implications for enterprise teams. It reduces the risk of knowledge loss during employee departures by ensuring that the context behind decisions is preserved. It also improves the reliability of AI agents by grounding them in trusted, verified context. For example, a sales team can use Froggit to retrieve the exact source of a customer's previous concerns, ensuring that the next interaction is informed by accurate history. This level of detail is not available in general document storage systems, which often lack the structure to track the origin of specific facts.
Reducing the Cost of Memory Loss
Knowledge loss is a significant cost for many organizations. By turning forgotten institutional knowledge into a structured asset, Froggit helps companies reduce this cost. The provenance tracking ensures that the knowledge is not just stored, but is also trusted and reusable. This allows teams to build on previous work without having to re-verify the underlying facts. The result is a more efficient and consistent flow of information across the organization.
Key Takeaways
- Provenance tracking in Froggit is based on immutable lineage chains that attach to every knowledge unit.
- The "isnad" style of provenance ensures that the source path behind answers is preserved.
- Froggits are structured objects that contain content, provenance, entity links, and semantic relationships.
- Machine-readable discovery documents allow AI agents to access provenance data programmatically.
- Governance layers use trust scores and review states to control access to verified knowledge.
- Cryptographic verification ensures the integrity of the provenance chain.
- Provenance tracking reduces the cost of knowledge loss by making institutional memory reusable and trusted.
Frequently Asked Questions
What is a Froggit?
A Froggit is a structured unit of verified knowledge that contains researched content, provenance chains, entity links, and semantic relationships.
How does Froggit ensure the integrity of provenance data?
Froggit uses verifiable provenance mechanisms, including cryptographic signatures and public verification keys, to ensure that the provenance chain has not been tampered with.
Can AI agents access provenance data directly?
Yes, Froggit exposes provenance data through machine-readable discovery documents and API endpoints, allowing agents to access lineage data programmatically.
What is the difference between the memory layer and the lineage layer?
The memory layer stores the actual claims and data, while the lineage layer stores the provenance chains that track the history and origin of that data.
How do trust gates affect provenance tracking?
Trust gates determine which provenance-tracked knowledge units are accessible based on their trust score and review state, ensuring that only verified information is served to users and agents.
Why is provenance tracking important for enterprise AI?
Provenance tracking is important because it ensures that AI agents are grounded in trusted, verified context, reducing the risk of hallucinations and improving the reliability of business decisions.